Risk analysis: understanding risk, probability, and uncertainty
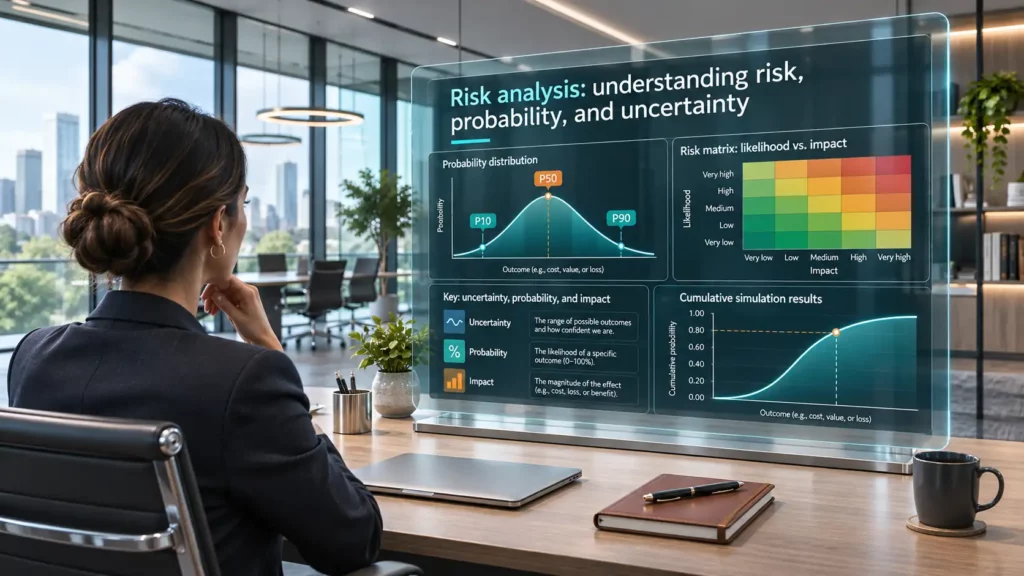
Risk analysis is the practice of estimating what can go wrong, how likely it is, and how bad it would be, so you can decide what to do about it. Its raw material is uncertainty, and its language is probability. A single best estimate hides the range of what might happen, a trap that Sam Savage named the flaw of averages.
Consider a hypothetical schedule with two tasks that run in parallel. Each task has a 50 percent chance of finishing within 10 days, so the plan shows 10 days for each task and 10 days for the project. The project finishes within 10 days only if both tasks do, and with independent tasks, that happens 25 percent of the time. The plan looks reasonable, and it runs late three times out of four.
This page defines the terms, shows how to express uncertainty as a probability distribution, and explains why experts misjudge what they know.
What is the difference between risk and uncertainty?
Uncertainty is what you do not know. Probability is the language that expresses it, a number between 0 and 1 that states how strongly you expect an event to happen. Risk is uncertainty about outcomes that matter to you, usually losses.
The three words work at different levels. Everyone who faces the same unknown faces the same uncertainty, but risk depends on what you stand to lose. Rain next week is one shared uncertainty, yet a crop in the field carries a risk that a crop in the barn does not.
S. Kaplan and B. John Garrick turned this into a working definition in 1981. To describe a risk, they argued, you must answer three questions: what can happen, how likely is it, and what are the consequences? Each scenario then becomes a triplet of an event, a likelihood, and a consequence, and the risk is the full set of triplets.
The economist Frank Knight drew a sharper line in 1921. He reserved risk for situations where you know the odds, as with a roulette wheel, and uncertainty for situations where you do not. Practical analysis rarely keeps that line, because you can express a lack of knowledge as a probability too, and the numbers then guide decisions.
What kinds of uncertainty are there?
Uncertainty comes in two main kinds. Aleatory uncertainty is natural variability, such as a wind farm’s hourly output or the number of calls to a service desk. Epistemic uncertainty is lack of knowledge, such as an unmeasured soil property or a cost that nobody has quoted yet.
The difference decides what more effort can fix. More data narrows epistemic uncertainty, because the quantity has one true value that you have not learned yet. More data cannot remove aleatory uncertainty, because next week’s wind will still vary, although it does sharpen your estimate of the range.
Two further kinds deserve attention. Model uncertainty asks whether the structure and equations you chose describe reality, which no input range can tell you. Uncertainty about values asks what you want, because different stakeholders weigh the same outcomes differently.
In practice, the boundaries blur, so many analysts label an uncertainty by what they can do about it. Morgan and Henrion’s book Uncertainty treats each kind in depth.
Qualitative or quantitative: which approach fits?
Qualitative analysis rates risks on a scale such as low, medium, and high, and plots them on a risk register or heat map. Quantitative risk analysis, which some fields call quantitative risk assessment, expresses each uncertainty as a probability distribution and calculates the range of outcomes, usually with simulation.
Both have a place. Qualitative methods suit early screening, because they run fast, need little data, and help a group agree on which risks deserve attention. Quantitative methods suit costly decisions and interacting risks because a high rating doesn’t say how high, and two medium risks can combine into one that isn’t.
Heat maps also compress information. One cell labeled high could hold a 5 percent chance of losing $50 million, and another cell labeled high could hold a 50 percent chance of losing $5 million. Both carry an expected loss of $2.5 million, yet they call for different responses.
A sensible path starts qualitative and moves to numeric when the stakes justify the effort. Lumina’s comparison of risk analysis software reviews tools for both approaches.
How do you express uncertainty as a probability distribution?
The practical route starts with three numbers: the 10th, 50th, and 90th percentiles, usually written P10, P50, and P90. P50 is the middle value, which the outcome is equally likely to fall above or below. P10 is a low value that the quantity falls under one time in ten, and P90 is a high value that it exceeds one time in ten.
Take a hypothetical project cost with a P10 of $8 million, a P50 of $11 million, and a P90 of $15 million. A triangular distribution built from those percentiles has a most likely value near $10 million, a median of $11 million, and a mean slightly above $11 million. A single figure of $10 million hides a one in ten chance of spending more than $15 million.
Next, choose a distribution family that matches how the quantity behaves. A triangular distribution suits a rough range with a most likely value, a lognormal distribution suits a positive quantity that skews to the right, and a uniform distribution suits a quantity where you can say only that every value between two limits is equally plausible. Analytica’s Triangular10_50_90 function builds a triangular distribution directly from the three percentiles.
Finally, combine data with judgment. Fit a distribution to data where you have it, and adjust it with expert judgment when conditions differ from the past.
What is overconfidence bias in expert judgment, and what can you do about it?
Overconfidence bias is the tendency to state ranges that are too narrow, so the true value falls outside them more often than the stated confidence implies. It affects experts and novices alike.
A 1986 study by Max Henrion and Baruch Fischhoff shows the pattern in physics. They compared published measurements of the speed of light between 1875 and 1958 with their stated 98 percent confidence intervals, and 11 percent of the 27 measurements fell outside, when about 2 percent should have. Careful scientists still understated their uncertainty.
Two other biases feed the problem. Anchoring leads experts to adjust a range around their first guess, and availability makes recent or vivid events seem more likely than they are.
Structured elicitation reduces these effects. Ask for the extremes first and the median last, so the range does not anchor on a best guess. Ask what would have to happen for the value to land outside the range, and widen the range when the answer comes too easily. When you combine several experts, Roger Cooke’s classical model gives them calibration questions with known answers and weights each expert by performance.
Lumina’s article on improving quantitative data with expert elicitation covers these practices in more detail.
How do you propagate uncertainty through a model?
Once each uncertain input has a distribution, the model must carry those distributions through to the result, which is the task of uncertainty analysis. Monte Carlo simulation does this by drawing thousands of random input combinations, running the model for each, and collecting the results into a distribution of outcomes. Latin hypercube sampling achieves accurate results with fewer runs by dividing each distribution into equal-probability slices and sampling each slice.
For rare, high-impact events, importance sampling steers more runs toward the extreme tail, so the estimate of a low-probability disaster does not depend on luck.
Lumina’s article on Latin hypercube vs Monte Carlo sampling compares the two sampling approaches, and readers who want to compare tools can read the comparison of Monte Carlo software.
Which uncertainties matter most?
A model may contain dozens of uncertain inputs, and only a few of them change the answer. Sensitivity analysis ranks the inputs by their effect on the result, so you spend your effort where it counts. Decision analysis goes further by asking whether an uncertainty could change which option you choose at all.
Value of information puts a price on that question, because an uncertainty deserves study only if learning its true value could change your decision. Max Henrion’s webinar, The value of knowing how little you know, covers the expected value of perfect information and the expected value of including uncertainty.
Where did probabilistic risk assessment come from?
Quantitative risk analysis took shape in nuclear safety. Norman Rasmussen led the Reactor Safety Study, which appeared in 1975 as WASH-1400 and estimated the probabilities and consequences of a major accident at a nuclear power plant. Its main innovation combined fault trees and event trees into one method. That approach became known as probabilistic risk assessment, or PRA.
Kaplan and Garrick published their definition of risk in 1981, in the first volume of the journal Risk Analysis, which Wiley publishes for the Society for Risk Analysis. NASA borrowed PRA from the nuclear industry for launch vehicles, ran its first Space Shuttle study with an industry partner in 1988, and built a model of overall Shuttle risk between 1996 and 1998. Tim Bedford and Roger Cooke’s 2001 book, Probabilistic Risk Analysis: Foundations and Methods, surveys the methods that grew from this history.
How does Analytica handle risk and uncertainty?
Lumina designed Analytica from the start to represent uncertainty, so you do not need a Monte Carlo add-in. An uncertain input is an ordinary variable with a probability distribution, which you choose from a menu or define by percentiles. Analytica generates the resulting distribution of outcomes automatically whenever you view a result.
Its default sampling method is median Latin hypercube, and importance sampling handles rare but high-impact events. Intelligent Arrays let one model carry uncertainty across time periods, regions, and alternatives without copying its structure.
Two examples show the range of this work. Lumina and NASA’s Kennedy Space Center built the Schedule and Cost Risk Analysis Modeling system, SCRAM, on Analytica to identify the importance of major delays in Shuttle ground processing, and NASA’s Spinoff account of SCRAM describes the project. The ANAGRAM case study describes a model that ranks gas pipeline mitigation projects by risk spend efficiency, the risk reduction per dollar that California utilities have used, and it relies on Sparse Monte Carlo to simulate rare failures. Lumina’s energy and power page covers more work for utilities.
Lumina’s risk and uncertainty hub gathers articles, webinars, and case studies, and the page on how Analytica lets you embrace risk and uncertainty explains the approach.
Further reading
The sources below cover the definitions, methods, and history on this page.
- Morgan, M. G., and M. Henrion. Uncertainty: A Guide to Dealing with Uncertainty in Quantitative Risk and Policy Analysis. Cambridge University Press, 1990.
- Bedford, T., and R. Cooke. Probabilistic Risk Analysis: Foundations and Methods. Cambridge University Press, 2001.
- Kaplan, S., and B. J. Garrick. “On the Quantitative Definition of Risk.” Risk Analysis, volume 1, number 1, 1981.
- Henrion, M., and B. Fischhoff. “Assessing Uncertainty in Physical Constants.” American Journal of Physics, volume 54, pages 791 to 797, 1986.
- Knight, F. H. Risk, Uncertainty, and Profit. Houghton Mifflin, 1921.
- Colson, A. R., and R. M. Cooke. “Expert Elicitation: Using the Classical Model to Validate Experts’ Judgments.” Review of Environmental Economics and Policy, volume 12, number 1, 2018.
- Vose, D. Risk Analysis: A Quantitative Guide. 3rd ed. Wiley, 2008.
- Savage, S. L. The Flaw of Averages: Why We Underestimate Risk in the Face of Uncertainty. Wiley, 2009.
Morgan and Henrion’s book covers the uncertainty side of this work, and Bedford and Cooke cover the probabilistic risk assessment tradition.
Frequently asked questions
Is risk the same as uncertainty?
No. Uncertainty is what you do not know, and risk is uncertainty about outcomes that matter to you, usually losses. Probability expresses both, which is why a quantified risk is a set of outcomes with probabilities attached.
What is quantitative risk analysis?
Quantitative risk analysis expresses each uncertain input as a probability distribution and calculates the resulting range of outcomes, usually with Monte Carlo simulation. It answers questions that ratings cannot, such as the chance of exceeding a budget or the expected loss from a hazard. You can also rank which inputs drive the result, so you know where to reduce uncertainty.
Is a risk register enough?
A risk register works for screening and for keeping a group aligned on what could go wrong. It falls short when the decision is costly, when risks interact, or when you need to know how large a loss could grow. In those cases, a register tells you what to model, and a quantitative analysis tells you what the model implies.
How do you get probabilities when there is no data?
Ask experts for ranges, using the P10, P50, and P90 questions, and use the structured practices above to counter overconfidence. Look for similar past cases, even loosely similar ones, and use physical or logical limits to set bounds. Then revisit the distributions as data arrives, because a judgment-based distribution is a starting point, not a final answer.
What is a P90 estimate?
A P90 estimate is the 90th percentile of a distribution, the value that the quantity stays below 90 percent of the time. For a cost, P90 gives a conservative budget with a one-in-ten chance of overrun. Some fields, such as oil and gas and renewable energy yield, define P90 the opposite way: the value you exceed 90 percent of the time, so check the convention before you compare numbers.
Author
 Max Henrion, PhD, Founder and CEO of Lumina Decision Systems, originated Analytica and has led decision-support work across energy, environment, healthcare, and aerospace. He holds a PhD from Carnegie Mellon University, a Master of Design from the Royal College of Art, and a degree in Natural Sciences from Cambridge University, and is an Adjunct Professor at Carnegie Mellon’s Department of Engineering and Public Policy. He received the 2018 Frank Ramsey Medal from the Decision Analysis Society for lifetime contributions to the field.
See also
Visual modeling
What is Analytica?
How to draw an influence diagram in 3 minutes